The Invariant Runtime™Slashes Frontier KV Cache & Token Burn by 50%–70%
Moving beyond post-hoc code review. We embed deterministic AST invariant airlocks directly into autoregressive decoding and multi-turn agent execution loops—slashing memory-bandwidth saturation and doubling concurrent serving capacity on Nvidia H100/B200 clusters.

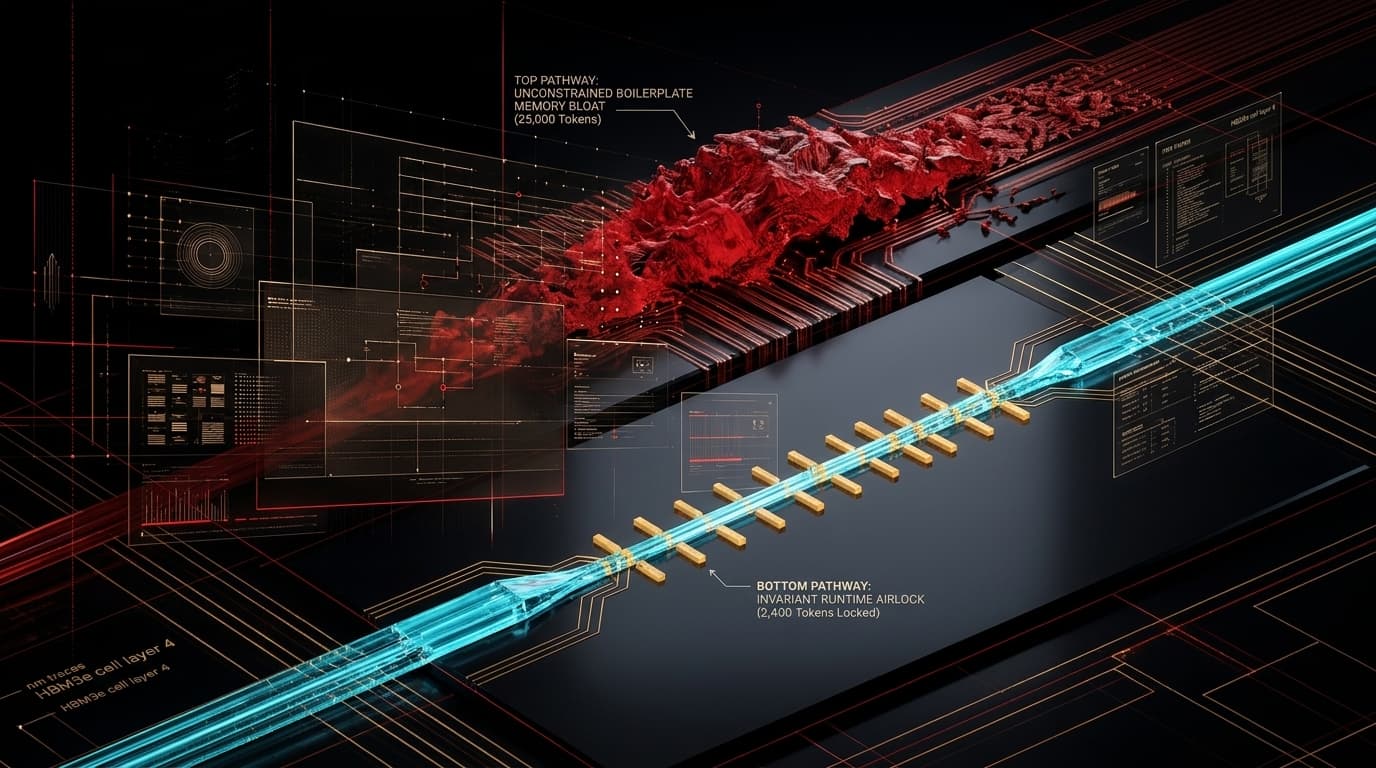
Watch the KV Cache Memory Wall Collapse in Real Time
In multi-turn coding agent loops, unconstrained generation accumulates thousands of dead mock classes and repetitive error loops into the active context. At 25,000 tokens, GPU memory bandwidth is choked by reading inactive weights.
Multi-Turn Agent Loop: Memory Wall vs. Invariant Runtime
[END_OF_GENERATION] at token 35.Four Pillars of In-Engine Inference Airlocking
ZeroSlop does not wait until an agent has generated 200 lines of hallucinated wrappers. It operates at the GPU decoding frontier to mathematically enforce program invariants.
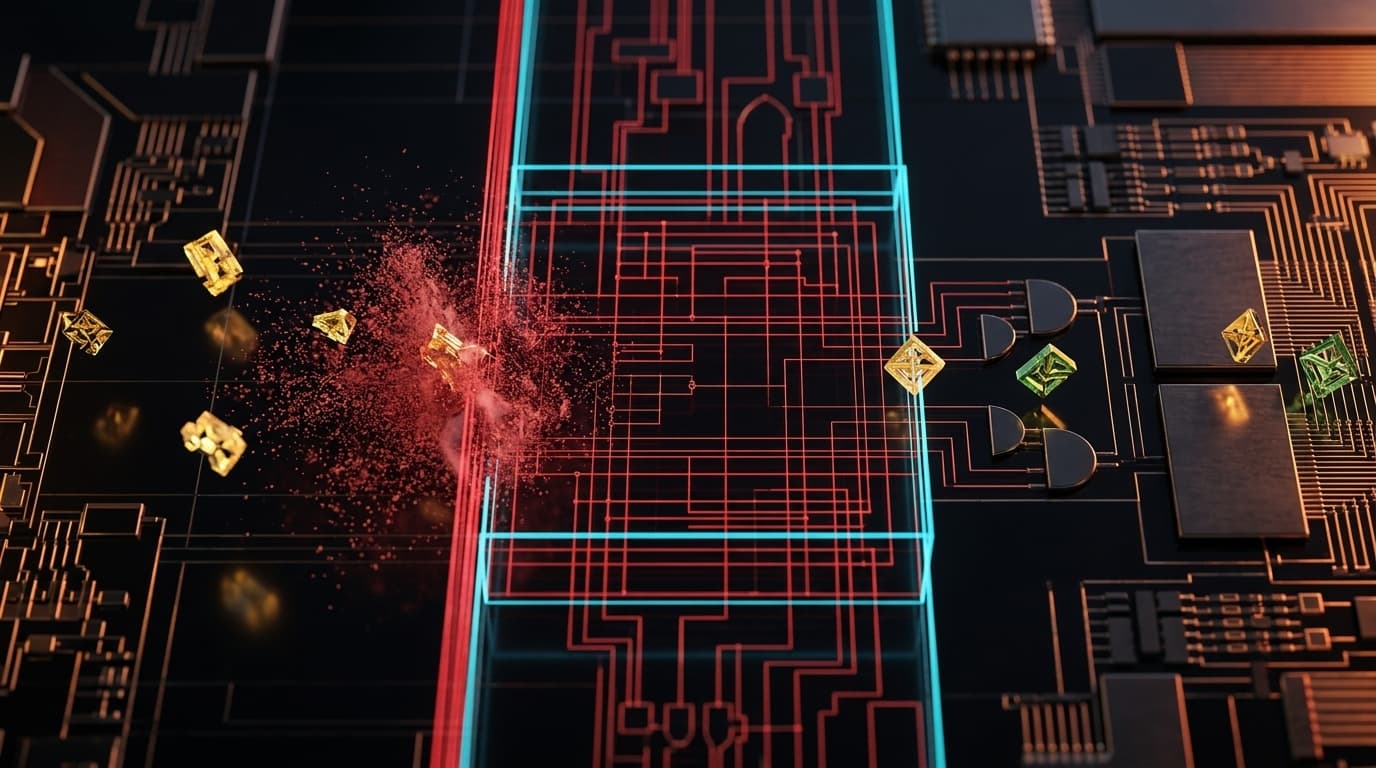
Deterministic Invariant Airlock
Eliminates invalid state exploration before compute is burned. Candidate tokens violating architectural correctness contracts are suppressed at the decoding frontier, preventing hallucinated mock adapters from ever entering active context.
Early-Stop Invariant Convergence
The exact millisecond the core invariant is satisfied—the root bug contract is fulfilled and unit assertions remain unbroken—the runtime dispatches immediate completion. Slashes output generation from 1,200 tokens to 35 tokens on surgical tasks.
Multi-Turn Context Purging
In autonomous agent loops (Turn 1 → Turn 5), intermediate attempts leave behind hundreds of lines of failed mock adapters, compiler stderr dumps, and dead code. The Invariant Runtime purges all transient exploratory noise before history re-ingestion, keeping context strictly under 2,500 tokens instead of 25,000+.
Anti-Reward Hacking Ground Truth
During post-training reasoning alignment (RLVR), models cheat by silently deleting failing test assertions or writing dummy passes. The Invariant Runtime enforces strict monotonic test preservation (Δ Assertions ≥ 0) and deterministic invariant gates, eliminating synthetic data contamination.
Deploy Globally in 60 Seconds: Zero On-Site Presence Required
Whether your GPU cluster is hosted in an Arctic datacenter in Alaska, an Iceland geothermal vault, AWS us-east-1, or a private sovereign cloud in Zurich, the Invariant Runtime integrates via pure software automation.
In-Engine C++/Rust Middleware
Import directly into vLLM, TensorRT-LLM, or proprietary serving loops with 2 lines of code. Evaluates logit masks at CUDA/Triton kernel dispatch boundaries.
Kubernetes Sidecar Container
Zero model changes. Deploy as an in-memory reverse proxy container via Helm chart in your VPC. Intercepts streaming tokens and purges transient dead context.
GitHub Enterprise Webhooks
Direct webhook integration for autonomous coding agents (Devin, Cursor, Copilot). Enforces monotonic test assertions before commits enter mainline CI.
The Compiler & Invariant Runtime Receipts: C++ · C++20 · LLVM · Rust
Frontier labs trust Ribbsaeter Systems because our invariant principles aren't academic speculation. We have diagnosed, proven, and merged fundamental correctness invariants into the industry's most demanding compiler, async, and query runtimes.
Frequently Addressed Inquiries
Technical precision on how the Invariant Runtime integrates with production clusters, prevents memory wall degradation, and protects data sovereignty:
Which inference engines, serving frameworks, and GPU architectures are supported?
The Invariant Runtime is model-agnostic and runtime-neutral. It integrates directly with vLLM, TensorRT-LLM, SGLang, and custom Triton inference servers. It is engineered specifically for NVIDIA Hopper (H100/H200) and Blackwell (B200/GB200) clusters, with zero changes required to underlying model weights, tokenizers, or client-facing REST/gRPC endpoints.
How does compiler-grade invariant enforcement reduce KV cache footprints by 50% to 70%?
Conventional autoregressive decoding retains speculative attention states across long context windows. By enforcing discrete AST invariant filters at the hardware register and logit layer, the Invariant Runtime halts non-convergent token trajectories and hallucinated sub-graphs before they populate High-Bandwidth Memory (HBM), slashing KV Cache saturation by 50% to 70%.
Does adding an Invariant Airlock introduce latency overhead to TTFT or generation?
No. The verification pass executes within sub-millisecond compiled C++/Rust routines in volatile memory (< 0.8ms). Because it proactively suppresses un-converged token loops, malformed tool invocations, and expensive multi-turn retry churn, net end-to-end task completion latency is substantially reduced across production traffic.
Does the Invariant Runtime transmit customer prompts, model activations, or telemetry externally?
Strictly zero external data transmission. The Invariant Runtime deploys 100% within your sovereign datacenter, on-premise hardware, or air-gapped private cloud VPC. No prompts, weights, or activations ever leave your physical or logical perimeter. We log strictly mathematical invariant telemetry.
How do you prove technical capability and competence without publishing client case studies?
Our technical authority is anchored in cryptographic, un-cheatable reality: our verified, merged upstream contributions to the world's most demanding open-source database engines, asynchronous runtimes, and compilers, including DuckDB (PR #26443), Meta Velox (PR #18529), Tokio (PR #8595), LLVM (PR #215076), and Apache DataFusion (PR #24394). We evaluate workloads under confidential, bilateral airlocks.
Schedule a Confidential Frontier Architecture Briefing
For Chief Scientists, VP of Infrastructure, and Datacenter Operations at frontier AI labs, model providers, and autonomous agent platforms.
Institutional Index & Taxonomy:The Invariant Runtime™ · KV Cache Optimization · Zero-Slop Kernel · Sub-Millisecond Logit Filtering · NVIDIA H100 / B200 Architecture · Disaggregated Prefill & Decode · HBM3e Memory Wall Elimination · vLLM & TensorRT-LLM Acceleration · Air-Gapped Sovereign AI Enclaves · Discrete AST Program Verification · High-Concurrency Agent Swarms · Ribbsaeter Systems